A crawler that respects the site
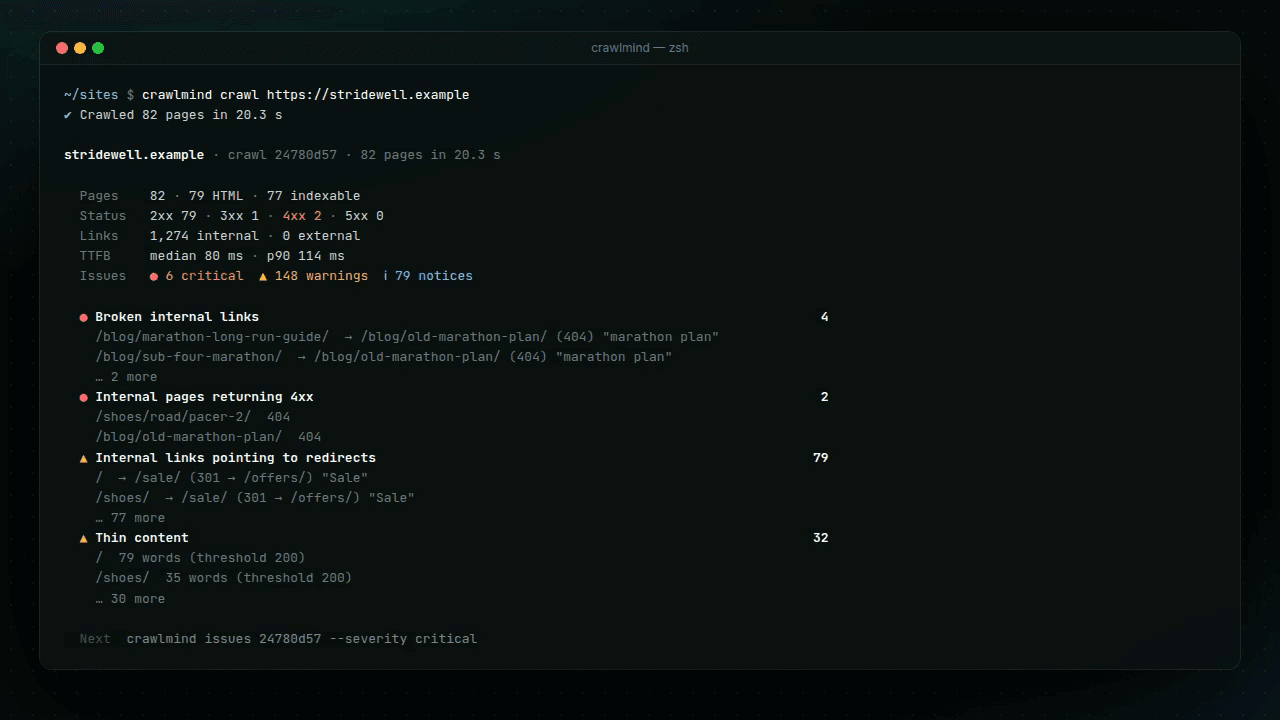
Crawlmind follows links and sitemaps, obeys robots.txt and Crawl-delay, and pauses between requests to the same host. For every page it records the redirect chain, response time, title, canonical, headings and each link with its place on the page: menu, footer or content. It reads HTML as the server sends it and does not run JavaScript.